SLAI, Huawei & NJU Unveil CANN-Bench to Forge Ascend Kernel Ecosystem
On July 17, 2026, Shenzhen Loop Area Institute (SLAI), Huawei, and Nanjing University (NJU) jointly launched CANN-Bench—an Ascend kernel public evaluation platform—and simultaneously released the first public leaderboard for Ascend C kernel code. The launch marks a pivotal leap for SLAI in AI systems, transitioning from "writing kernels" to "quantitatively evaluating them" and simutaneously boosting AI talent cultivation and industry-academia collaboration.
Bridging Models and Chips Through the Kernel Ecosystem
Kernels are the fundamental units enabling AI models to execute matrix computations and other computations. Their quality directly determines model correctness, performance, and computational efficiency. The kernel ecosystem serves as the hub connecting upper-layer models with underlying chips and underpins domestic AI innovation. As LLMs and AI agents evolve, the barrier to Ascend C kernel development is crumbling fast. From basic elementwise kernels to highly complex FlashAttention kernel, they now autonomously generate full code, drastically cutting R&D cycles.
Yet new challenges have emerged:
Which model produces better kernels? Is the generated code more reliable? How stable and efficient are the resulting kernels?
CANN-Bench addresses these questions head-on.Centered on a public leaderboard, it runs over 50 standardized evaluation tasks on code submitted by developers and teams under unified and reproducible evaluation criteria. It delivers quantitative scoring across multiple dimensions, including compilation correctness, precision pass rate, and computational efficiency, and publicly ranks the results.
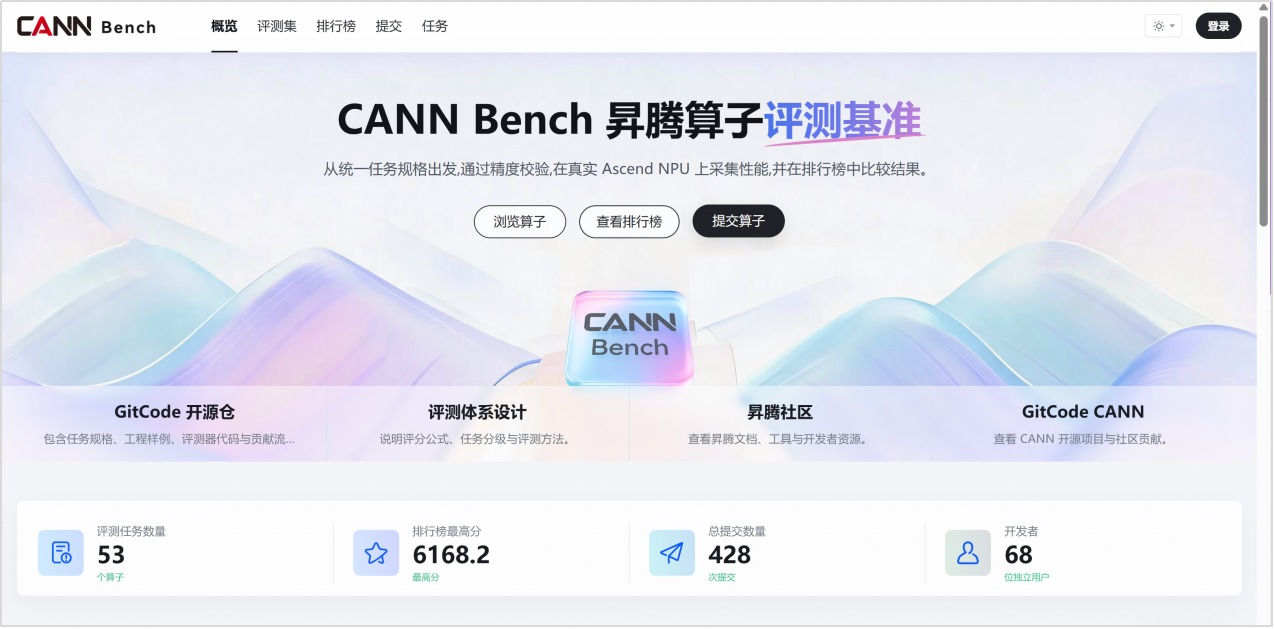
Figure 1: CANN-Bench platform (https://cannbench.com)
(Click "Read More" to visit)
A Leaderboard for Fair Kernel Competition
CANN-Bench pioneers a three-dimensional evaluation framework across "layered benchmarking, horizontal comparison, and capability diagnosis". Developers and teams can submit code for L1–L4 difficulty-level tasks, with all results scored under unified criteria and publicly displayed.
• Ranking by difficulty (L1/L2/L3/L4):
From Introductory tasks to the toughest challenges, participants at every level can pinpoint their competitive standing.
• Filtering by model/agent name:
Users can quickly locate specific models or agents and compare competing solutions side by side.
• Breakdown by compilation, precision, and performance:
Beyond total scores, compilation errors, precision gaps, and execution time bottlenecks are visible at a glance.
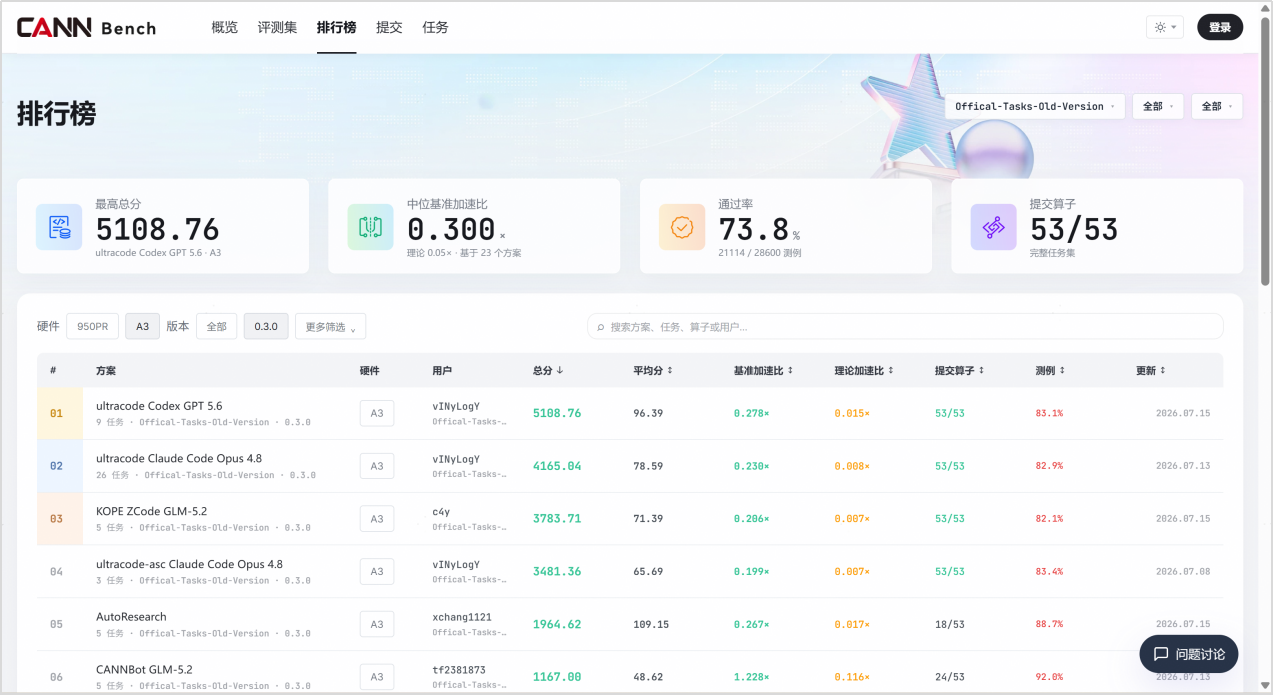
Figure 2: CANN-Bench platform leaderboard
A Standardized Evaluation Workflow Reliable from Local to Cloud
The CANN-Bench evaluation engine is fully aligned with its open-source repository, ensuring all kernels are measured against the same objective standards across three rigorous dimensions:
(1) Compilation correctness
Kernels must be compiled in a single pass on Ascend 910C/950PR chips. A compilation failure yields a zero score for that batch and automatically generates detailed error logs to help developers pinpoint issues.
(2) Precision pass rate
CANN-Bench deploys the industry-leading ULP (Unit in Last Place) error analysis framework rather than relying on simple thresholds.
• Normal value range:
Both Mean Relative Error (MRE) and Maximum Absolute Relative Error (MARE) are calculated. For float16 data, cross-validation is performed against 1 ULP as the standard threshold and 10 ULP as the maximum threshold; exceeding either results in failure.
• Small value range:
A dedicated decision logic is applied for the small value range when kernel outputs approach zero, avoiding numerical instability inherent in traditional relative errors.
• Special value scenarios:
Exact matching or specialized comparison algorithms are automatically applied for special floating-point values (Inf, NaN) and quantized data scenarios.
• Cancellation scenario:
A same-precision CPU reference mechanism is introduced to accurately assess precision loss caused by subtracting large numbers to produce small results—a classic precision trap.
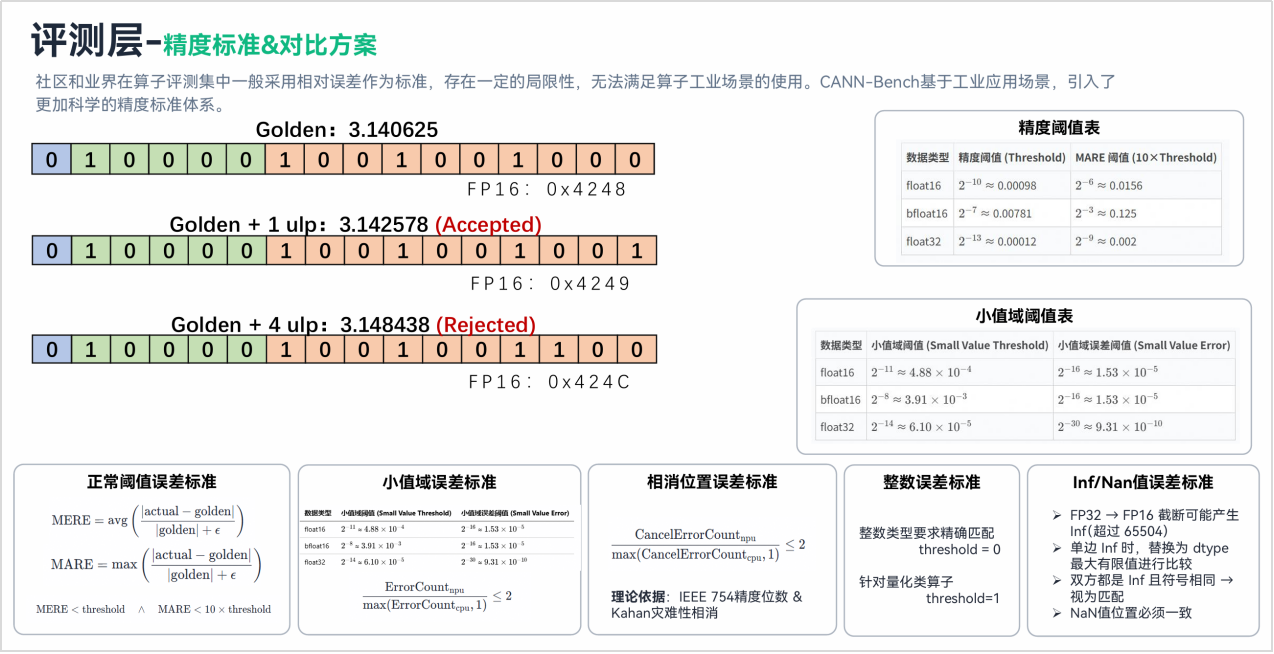
Figure 3: Precision standards and comparison scheme for the CANN-Bench platform
(3) Extreme performance
Anchored to theoretical hardware limits, CANN-Bench applies the proprietary HAP (Hardware-Anchored Performance) scoring formula, benchmarking measured kernel execution time against the NPU's theoretical performance upper bound. This approach completely eliminates gaming tactics such as "choosing slow baselines to inflate speedup ratios".
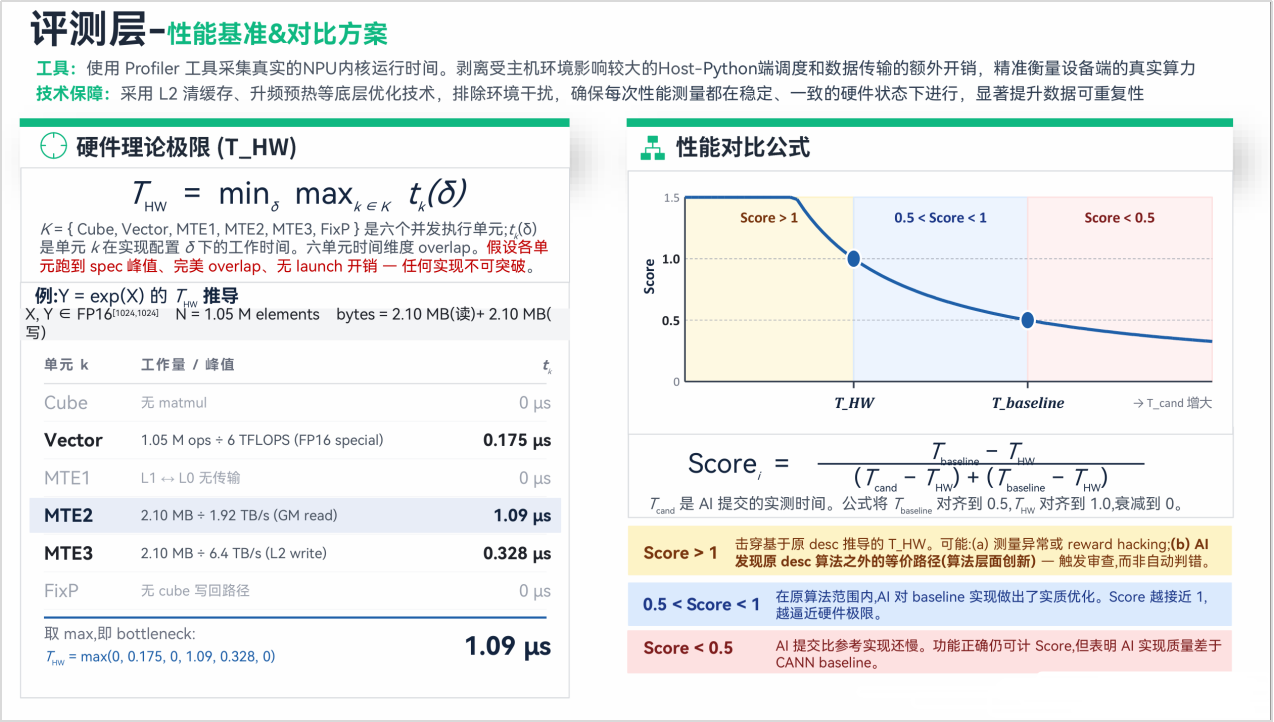
Figure 4: Performance benchmarks and comparison scheme for the CANN-Bench platform
Real-World Kernel Testing and Rapid Validation
CANN-Bench launches with two built-in benchmark suites: the full benchmark suite (Official-Tasks) and the quick validation suite (Micro-Official-Tasks). All kernels are derived from real-world business scenarios and categorized into four difficulty levels:
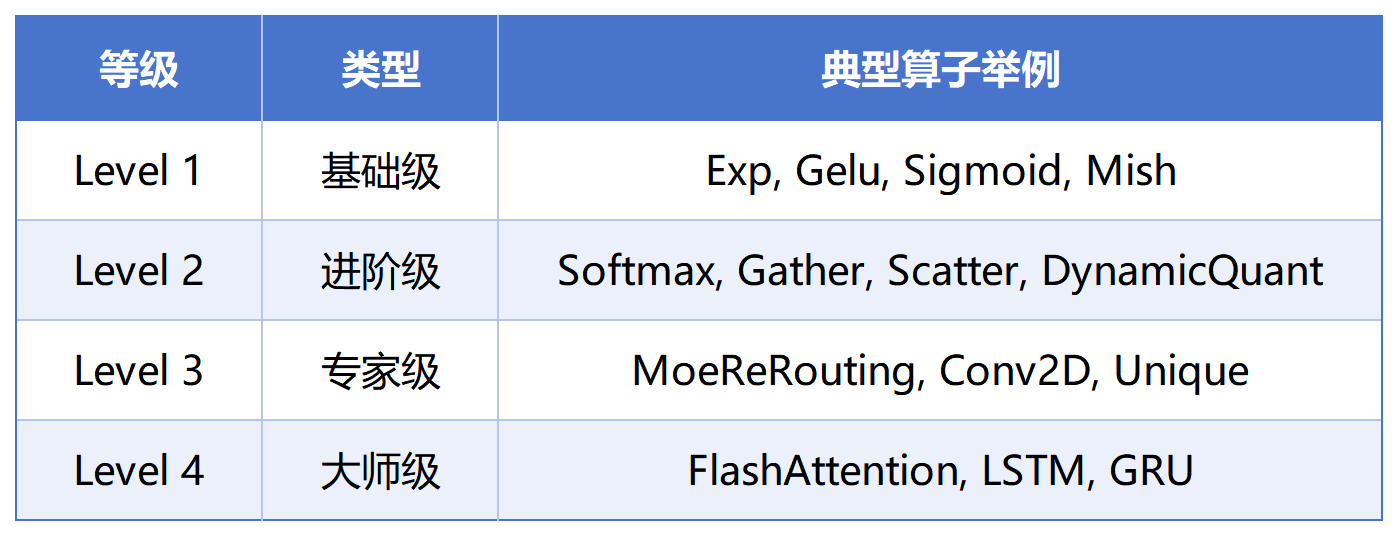
Table 1: Kernel difficulty levels
•Full benchmark suite:
The full suite spans over 50 real-world kernels, from basic SISO vector calculations to complex fused attention kernels that demand precise cube/vector unit scheduling. It fully benchmarks any AI model or agent across all dimensions.
•Quick validation suite:
The quick suite samples typical kernels across dimensions from the full suite, meeting developers' needs for rapid validation.
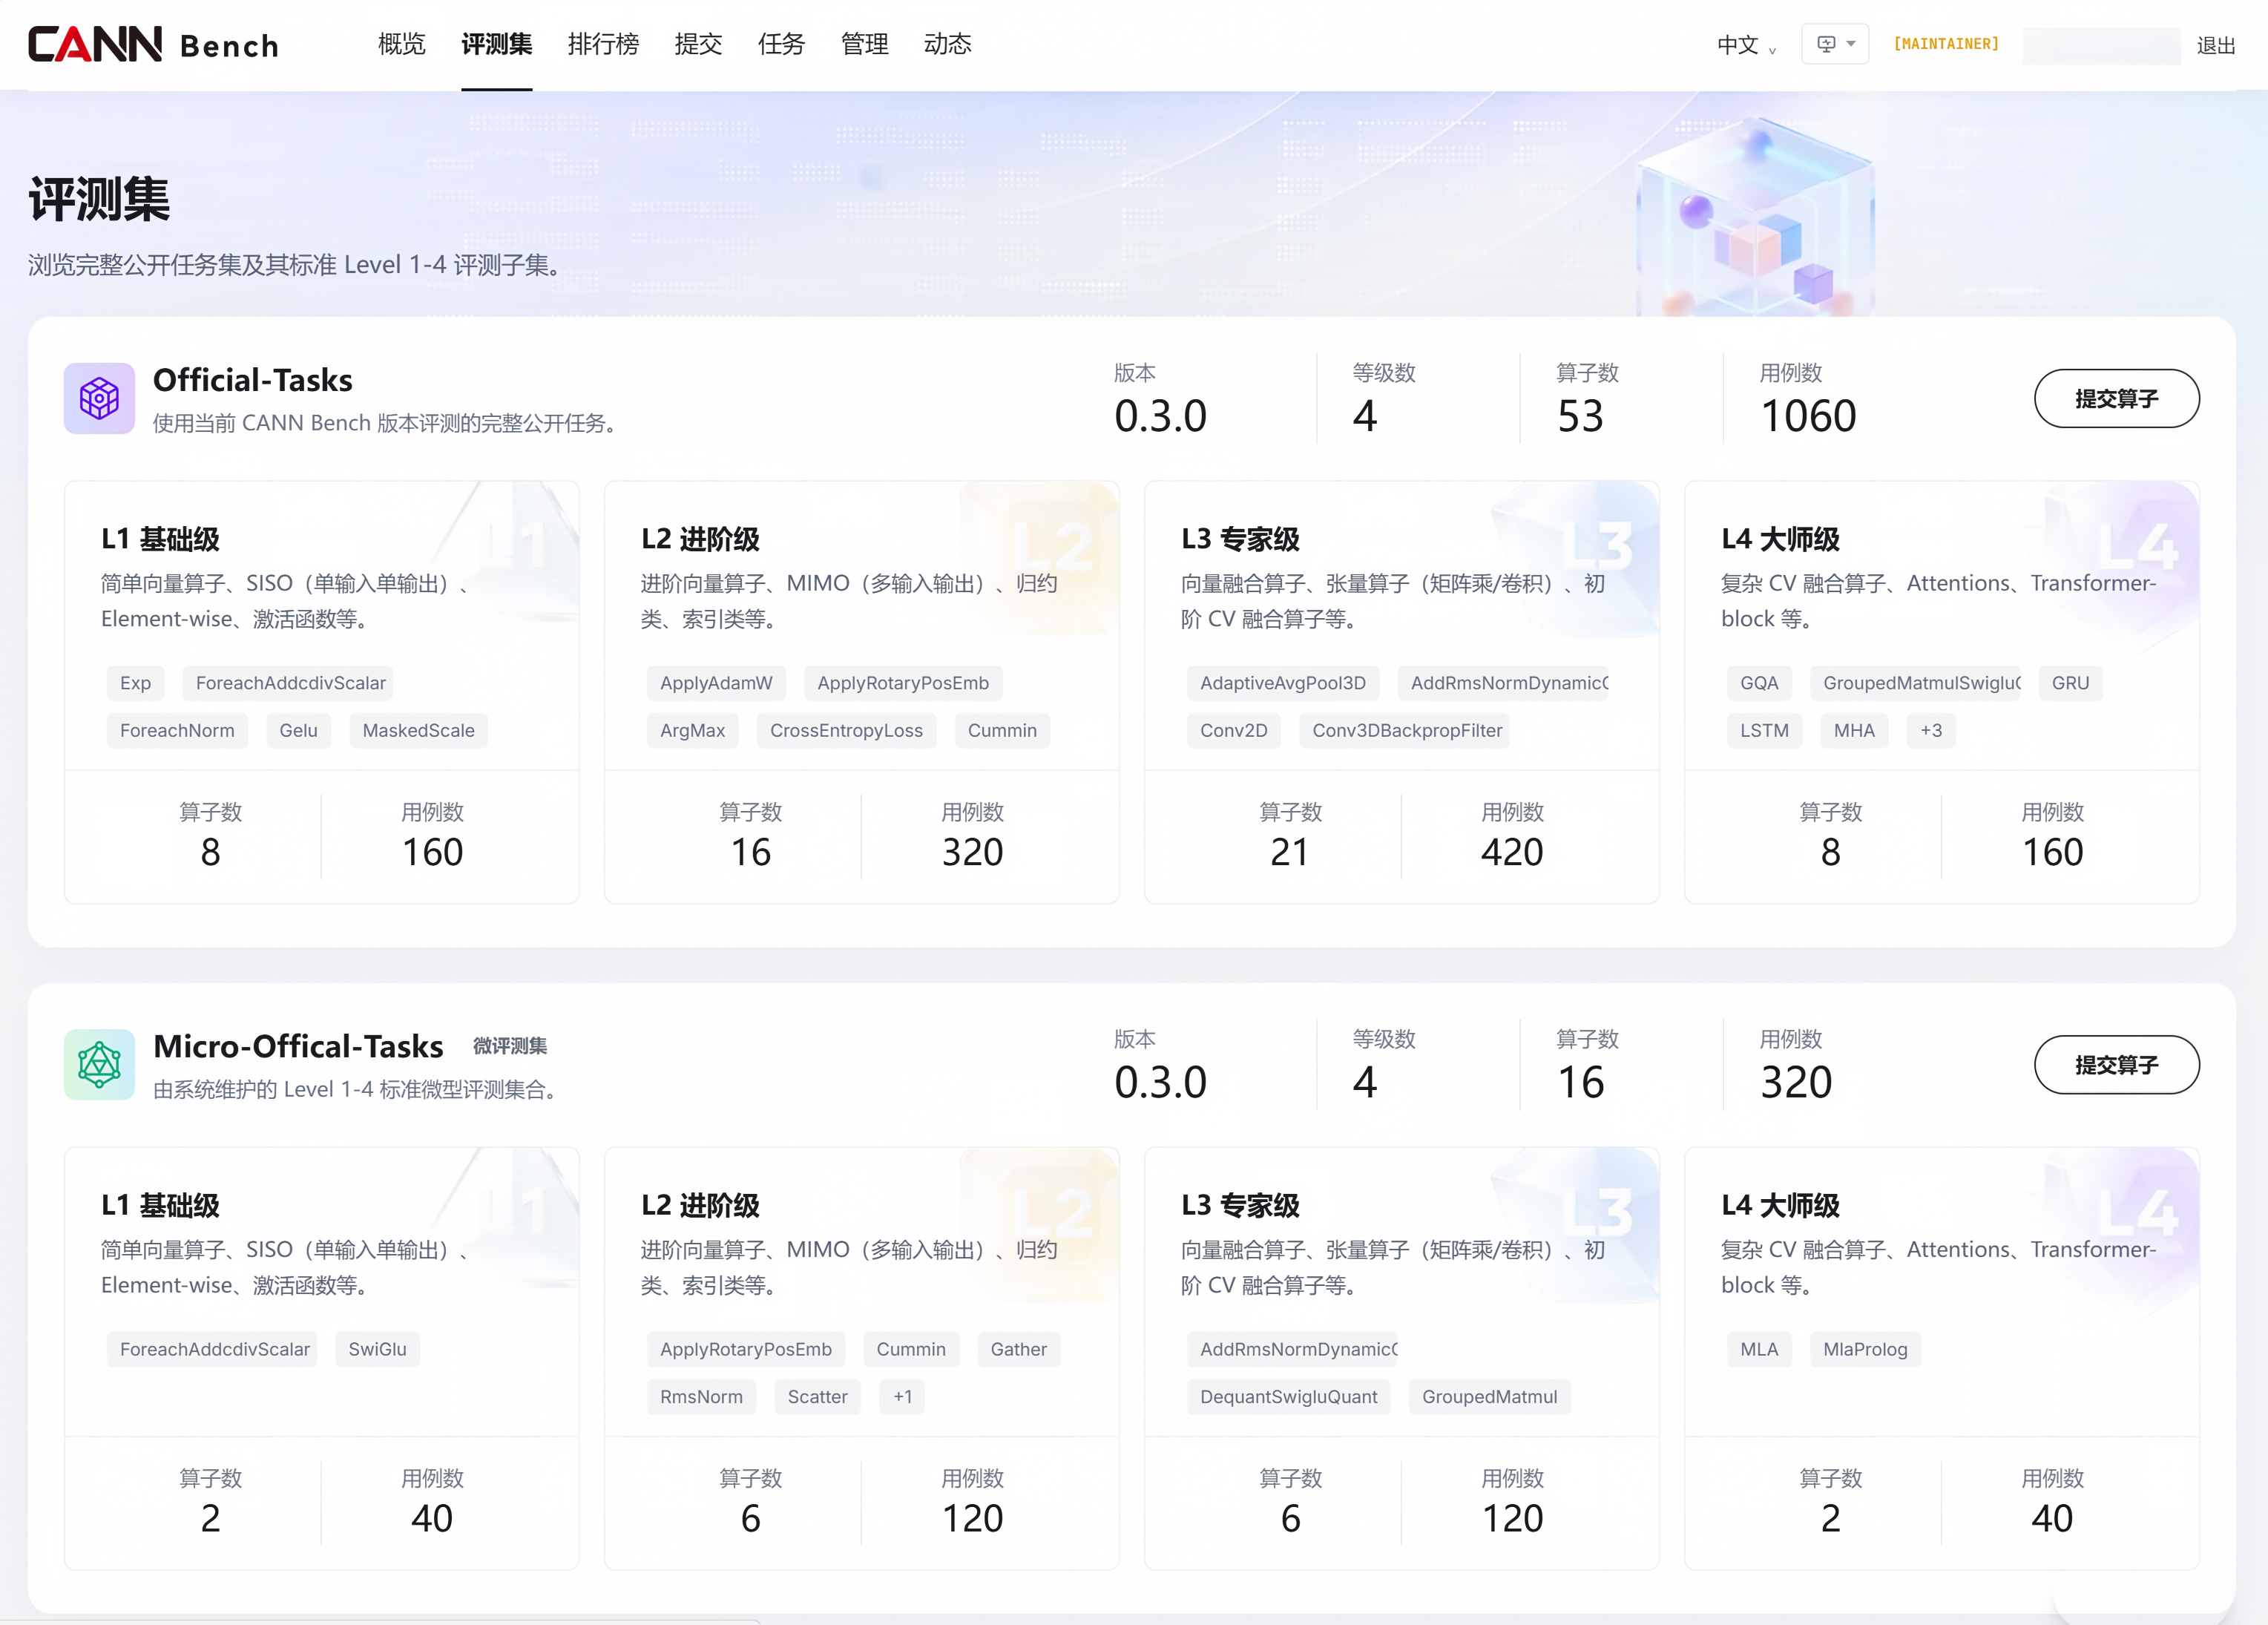
Figure 5: Benchmark suites for the CANN-Bench platform
CANN-Bench extends beyond building benchmarks, analyzing evaluation results, and allocating computing resources. Its true innovation also lies in enhancing the representativeness of evaluation tasks, standardizing workflows, and ensuring result reproducibility. This lays the groundwork for broader kernel coverage and deeper community engagement.
Open Source for a Thriving Ecosystem
Fully open-sourced, CANN-Bench invites developers to customize it, contribute new evaluation tasks, expand dimensions, and optimize scoring algorithms. This evaluation framework helps identify kernel variances, performance bottlenecks, and optimization gains, providing an objective basis for trustworthy generation, efficient optimization, and cross-scenario migration of kernels.
But evaluation is not the final goal; it is a necessary stepping stone to that future. Going forward, the platform will build out a full-lifecycle support system for kernel development, optimization, migration, and reuse. The system will curate a reusable, evolvable asset library that meets the efficiency demands of large-scale model training and inference, unlocks the full computing potential of domestic chips, empowers talent development in AI systems, and provides long-term support for the independent innovation and sustained evolution of China's AI industry.
Join and Co-create the CANN Ecosystem
SLAI invites developers, universities, research institutions, and industry partners to join in driving the CANN ecosystem forward.
• CANN-Bench Platform:
• CANN-Bench Source Code Repository:
https://gitcode.com/cann/cann-bench
• Detailed Documentation About CANN-Bench:
https://gitcode.com/cann/cann-bench/tree/master/docs
CANN-Bench is more than an evaluation tool; it is a proving ground where developers push Ascend NPU chips to their limits.
Joint R&D Organizations:
Shenzhen Loop Area Institute, Huawei (Computing Platform Advance Team, Turing Business Department, and 2012 Labs), and Nanjing University