预告丨SLAI Seminar第五十五期
2026年9月23日(周三)下午2:30,深圳河套学院荣幸地邀请到清华大学深圳国际研究生院的于超助理教授,在B401教室带来主题为“具身智能强化学习训练与智能基础设施探索”的学术报告分享。诚挚欢迎学院师生及对该领域感兴趣的产学研界同仁参与讲座。
Title
具身智能强化学习训练与智能基础设施探索
Embodied Intelligence Reinforcement Learning Training and Intelligent Infrastructure Exploration
About the Speaker
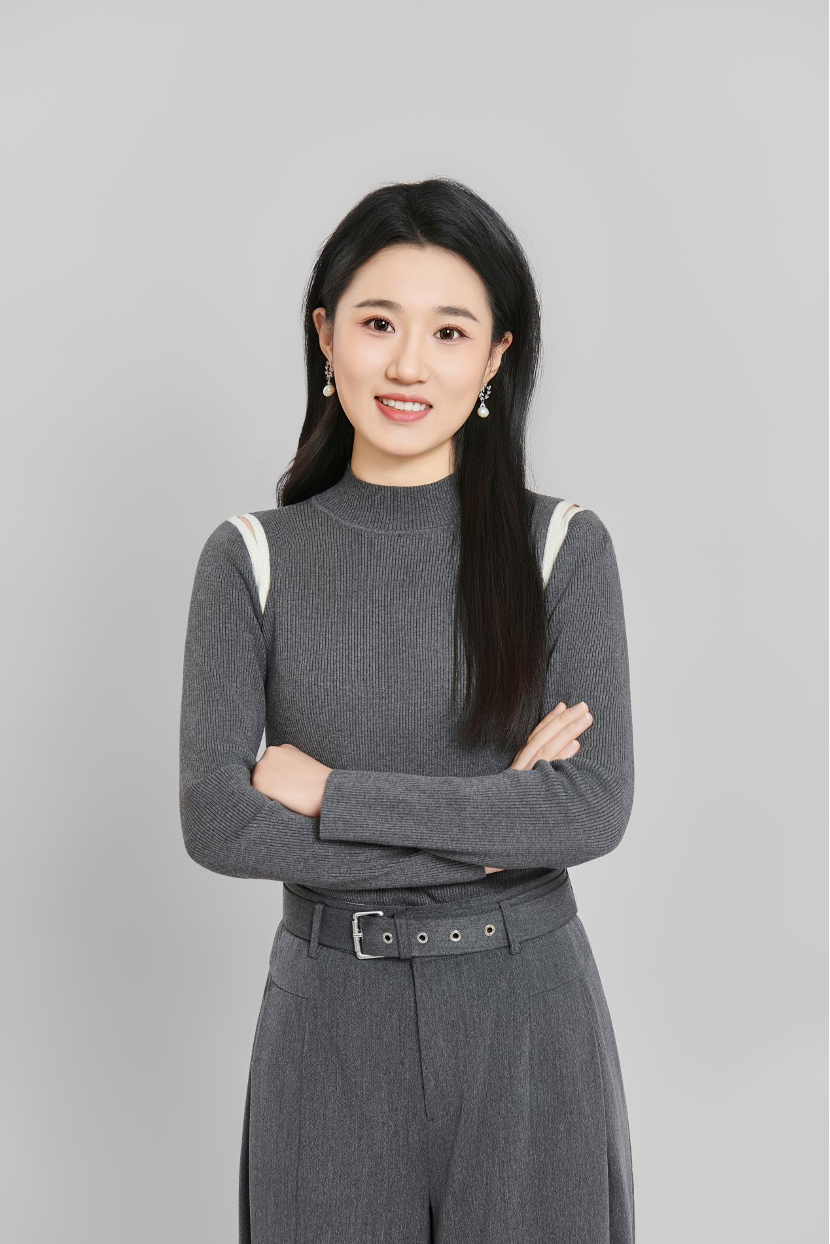
于超 助理教授
Asst. Prof. Chao Yu
于超是清华大学深圳国际研究生院助理教授(特别研究员)。入选中国电子学会青年托举工程。多年从事强化学习与机器人领域研究。以第一作者或通讯作者发表论文60余篇,谷歌学术引用量超7800次。在多智能体强化学习领域,以第一作者身份发表于NeurIPS 2022的 MAPPO算法,谷歌学术引用量已超4000次,被国内外顶尖高校纳入课程教学。作为通讯作者,她在ICML 2024上汇报了大模型强化学习训练算法相关研究(口头报告,录用率前 1.5%),该成果与OpenAI、Anthropic等顶尖学术机构的研究同台展示。她近期研发了首个面向具身智能的大规模强化学习框架RLinf,该框架已在GitHub开源,收获5000星标与700次复刻。它作为首个具身大模型训练引擎被英伟达的Isaac Lab正式收录,并已被多家头部企业与科研机构采用。
Chao Yu is an Assistant Professor (Special Research Fellow) at the Shenzhen International Graduate School of Tsinghua University. She has been selected for the Young Promoters Program of the China Electronics Society. She has been engaged in research in the fields of reinforcement learning and robotics for many years. She has published more than 60 papers as the first author or corresponding author, with over 7,800 citations on Google Scholar. In the field of multi-agent reinforcement learning, her MAPPO algorithm, published as the first author (NeurIPS 2022), has been cited over 4,000 times on Google Scholar and has been incorporated into courses at top domestic and international universities. As a corresponding author, she presented research on a large-model reinforcement learning training algorithm at ICML 2024 (Oral, top 1.5%). Her work has been presented alongside that of top academic institutions such as OpenAI and Anthropic. She has recently developed the first large-scale reinforcement learning framework for embodied intelligence, RLinf, which has been open-sourced on GitHub and has received 5,000 stars and 700 forks. It has been officially included by NVIDIA’s Isaac Lab as the first embodied large-model training engine and has been adopted by several top companies and research institutions.
Abstract
具身智能正从依赖大规模预训练模型能力的阶段,转向能够打造智能体,使其在真实世界中持续学习、自主执行并不断演化的新阶段。然而物理世界中的开放环境、长尾任务以及复杂交互过程,对现有的机器人学习范式提出了新挑战:一方面,强化学习为机器人通过环境交互获取经验、提升泛化能力提供了重要路径,但仍面临真机训练成本高昂、数据效率低、规模化部署困难等问题。另一方面,当前的视觉-语言-行动(VLA)模型虽然具备较强的语义理解与任务执行能力,但在开放环境下的任务泛化、长时序规划以及灵活适配方面能力仍存在局限,亟需全新的具身框架进一步释放其潜力。
本报告将围绕“具身智能强化学习训练与智能基础设施探索”展开研究。首先介绍面向具身基础模型的大规模强化学习训练基础设施,依托仿真与真机协同训练、异构资源调度、实体机器人在线学习,探究机器人策略持续优化与大规模演化的实现方法。随后介绍视觉-语言-行动(VLA)模型的智能基础设施,通过引入任务规划、记忆管理、技能抽象与可组合执行机制,将VLA从单一端到端策略转变为可智能调度、可组合、可持续迭代增强的执行模块。最后展望从“训练更强的模型”迈向“构建持续演化智能体”的未来方向,探索由强化学习训练基础设施与智能架构共同驱动具身智能发展的全新范式。
Embodied intelligence is transitioning from a phase where it relies on the capabilities of large-scale pre-trained models to one where it enables intelligent agents that can continuously learn, autonomously execute, and evolve in the real world. However, the open environments, long-tail tasks, and complex interaction processes in the physical world pose new challenges to existing robot learning paradigms: on one hand, reinforcement learning provides an important pathway for robots to acquire experience through environmental interactions and enhance their generalization capabilities, but it still faces issues such as high costs in real-world robot training, low data efficiency, and difficulties in scaling deployment. On the other hand, while current vision-language-action (VLA) models possess strong semantic understanding and task execution capabilities, their ability to generalize tasks in open environments, plan over long periods, and adapt flexibly remains limited. New embodied frameworks are needed to further unleash their potential.
This report will focus on "Embodied Intelligence Reinforcement Learning Training and Intelligent Infrastructure Exploration." First, it introduces large-scale reinforcement learning training infrastructure for embodied foundational models. Through collaborative simulation and real-world training, heterogeneous resource scheduling, and online learning by real robots, it explores methods for continuous optimization and large-scale evolution of robot strategies. Subsequently, it presents intelligent infrastructure for VLA (Vision-Language-Action) models. By introducing task planning, memory management, skill abstraction, and composable execution mechanisms, VLA is transformed from a single end-to-end strategy into an intelligently schedulable, combinable, and continuously enhanced execution module. Finally, it looks ahead to the future direction of moving from "training stronger models" to "building continuously evolving agents," exploring a new paradigm where reinforcement learning training infrastructure and intelligent architecture jointly drive the development of embodied intelligence.
Host
王祥丰 教授
Prof. Xiangfeng Wang
Date & Time
2026年9月23日(星期三)
下午2:30-4:00
September 23, 2026, Wednesday,
2:30pm-4:00pm
Venue
深圳河套学院B401教室
(深圳市福田区福保街道红棉路6号,地图导航“深圳河套学院-南门”)
Room B401, Shenzhen Loop Area Institute
(6 Hongmian Rd, Fubao Sub-Street, Futian District, Shenzhen, navigate to "Shenzhen Loop Area Institute (South Gate)" on the map.)
Online link
扫码加入会议
Join the Meeting Online
腾讯会议号:948-1135-4043
Tencent Meeting: 948-1135-4043